October 28, 2026
GitHub has released Copilot Fusion in GitHub Copilot, which orchestrates between Anthropic and OpenAI models. It scores 2 points below Opus 5.5 in Claude Code at half the Cost per Task in the Coding Agent Index
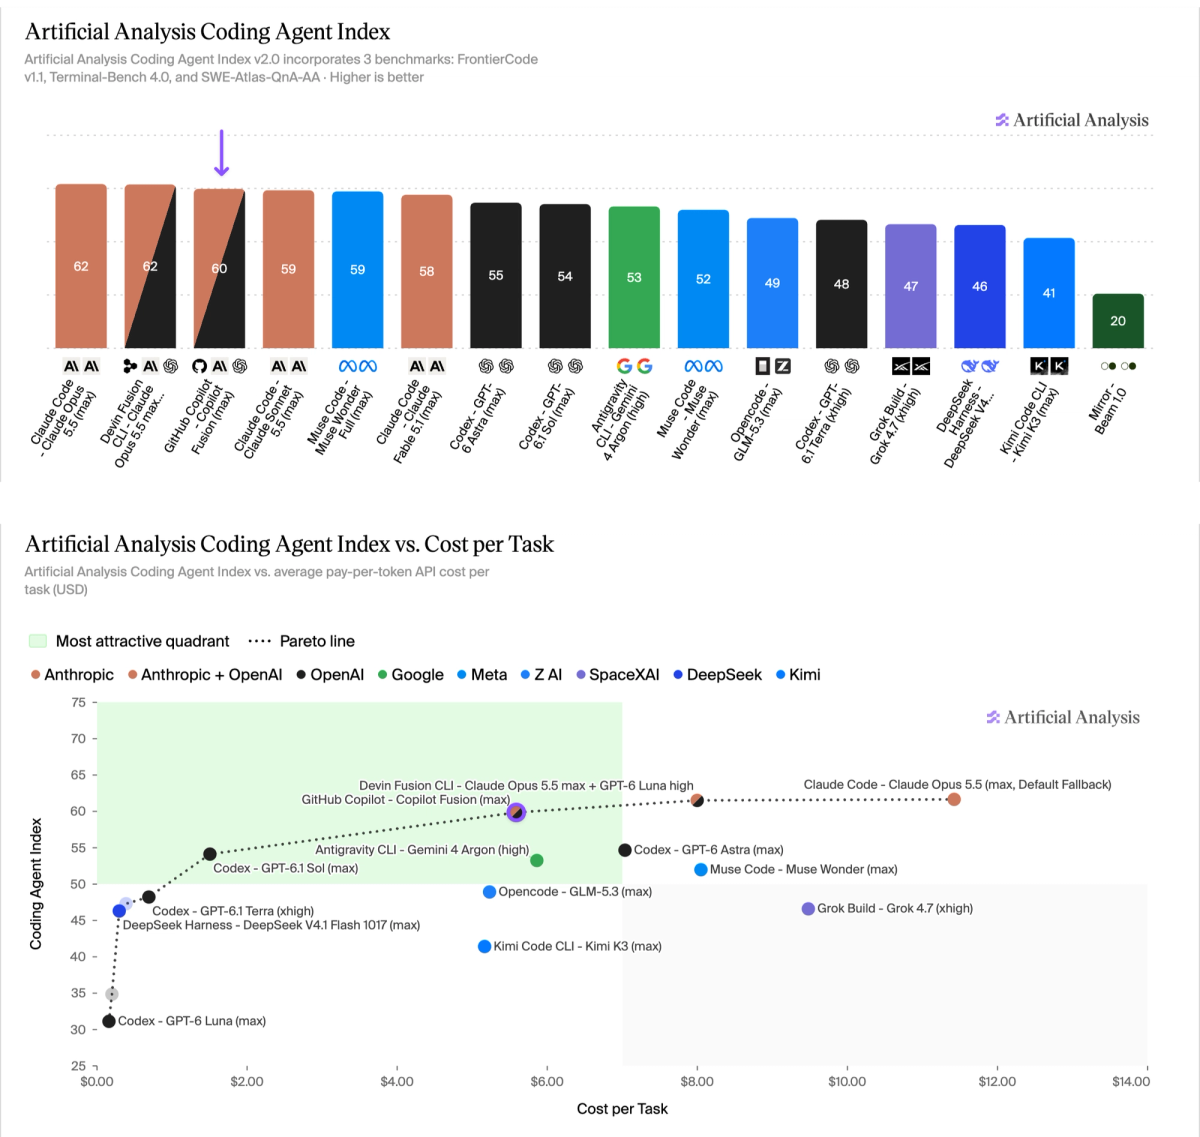
GitHub describes Copilot Fusion as a runtime orchestration system, which selects and coordinates models to optimize performance, cost, and latency for each task. Copilot Fusion chooses between a number of models from Anthropic and OpenAI, including Claude Opus 5.5, Claude Sonnet 5.5, GPT-6 Astra, and GPT-6 Sol. We benchmarked its max setting in GitHub Copilot CLI in the Artificial Analysis Coding Agent Index v2.0.
Token costs are charged based on the underlying models used to complete a request.
Key takeaways:
➤ Cost-efficient for near-frontier performance: Copilot Fusion in GitHub Copilot costs $5.59 per task, versus $11.42 for Claude Code with Opus 5.5 (max). Devin Fusion with Opus 5.5 (max) + GPT-6 Luna (high) scores 62 at $8.00 per task.
➤ Slight lead in Terminal-Bench 4.0: The Coding Agent Index v2.0 weights its three constituent benchmarks equally. Copilot Fusion in GitHub Copilot leads Terminal-Bench 4.0 with a score of 71. It ranks third on FrontierCode in the chart at 51, behind Claude Code with Opus 5.5 (max) at 56 and Devin Fusion with Opus 5.5 (max) + GPT-6 Luna (high) at 54. Its SWE-Atlas-QnA-AA score lags at 57, between GPT-6 Astra in Codex and Gemini 4 Argon in Antigravity CLI.
➤ Half the token use of Opus 5.5 in Claude Code: GitHub Copilot Fusion used 7.2M tokens per task in the Coding Agent Index, approximately half of the tokens used by Claude Opus 5.5 in Claude Code, and 30% less than Devin Fusion with Opus 5.5 (max) + GPT-6 Luna (high).
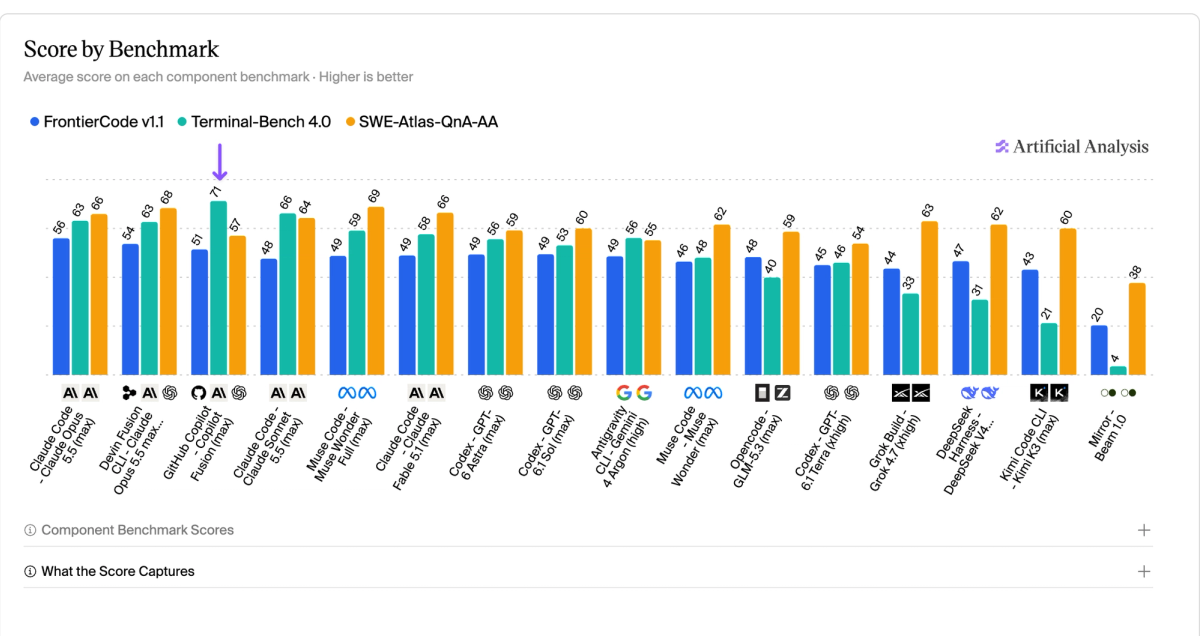
Copilot Fusion in GitHub Copilot lands with a slight lead in Terminal-Bench 4.0 with a score of 71. It ranks third on FrontierCode in the chart at 51, behind Claude Code with Opus 5.5 (max) at 56 and Devin Fusion with Opus 5.5 (max) + GPT-6 Luna (high) at 54. Its SWE-Atlas-QnA-AA score lags at 57, between GPT-6 Astra in Codex and Gemini 4 Argon in Antigravity CLI.
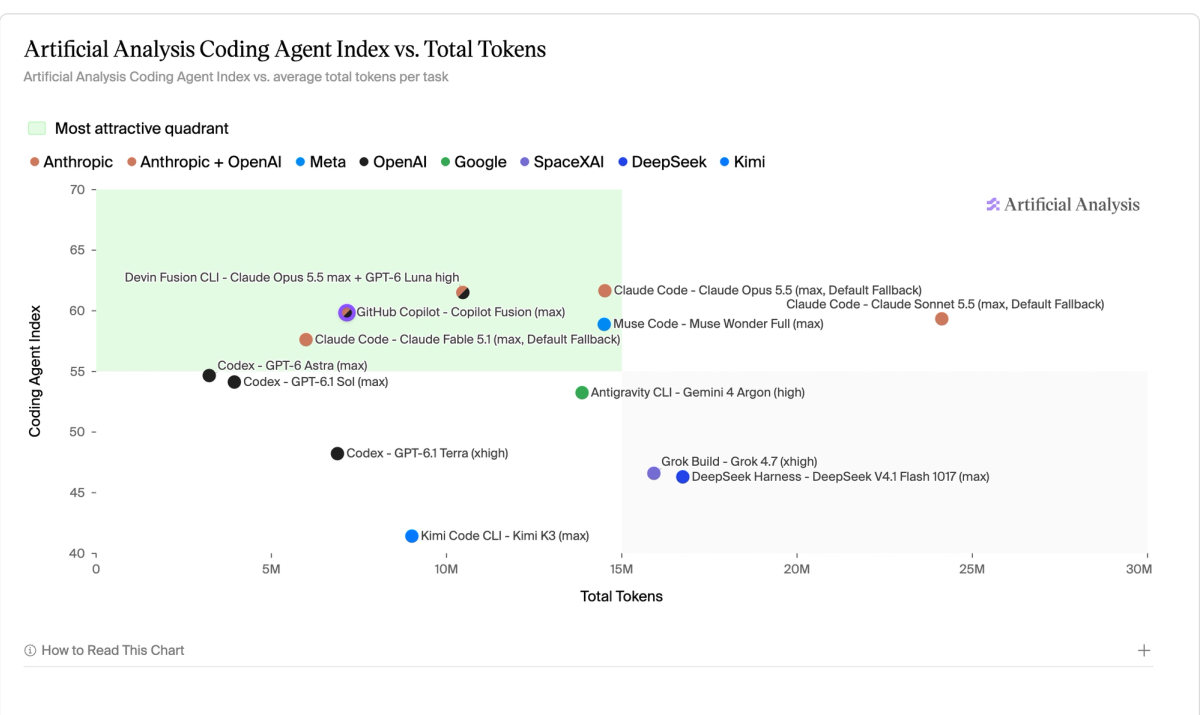
GitHub Copilot Fusion used 7.2M tokens per task in the Coding Agent Index, approximately half of the tokens used by Claude Opus 5.5 in Claude Code.
Explore the Coding Agent Index, task costs and benchmark results:
https://artificialanalysis.ai/agents/coding-agents?routers=true
Read the latest
Multimodal Knowledge Agent (MKA) benchmark: testing knowledge work capabilities with complex visual files
We’ve partnered with Google DeepMind to launch their Multimodal Knowledge Agent (MKA) evaluation, a new benchmark for agentic knowledge work over complex visual files
November 10, 2026
Endpoint Accuracy Index v1.1: Tighter long context intervals and expanded model coverage
We are launching the Artificial Analysis Endpoint Accuracy Index v1.1, a minor version upgrade alongside new coverage for GLM-5.3 Flash and Muse Spark Open.
November 9, 2026
Meta's Muse Ember is the cheapest model scoring 36 on the Intelligence Index
Meta's newest model Muse Ember scores 36 on the Artificial Analysis Intelligence Index, matching Claude Haiku 5.5 (max) at a third of the Cost per Task
November 9, 2026